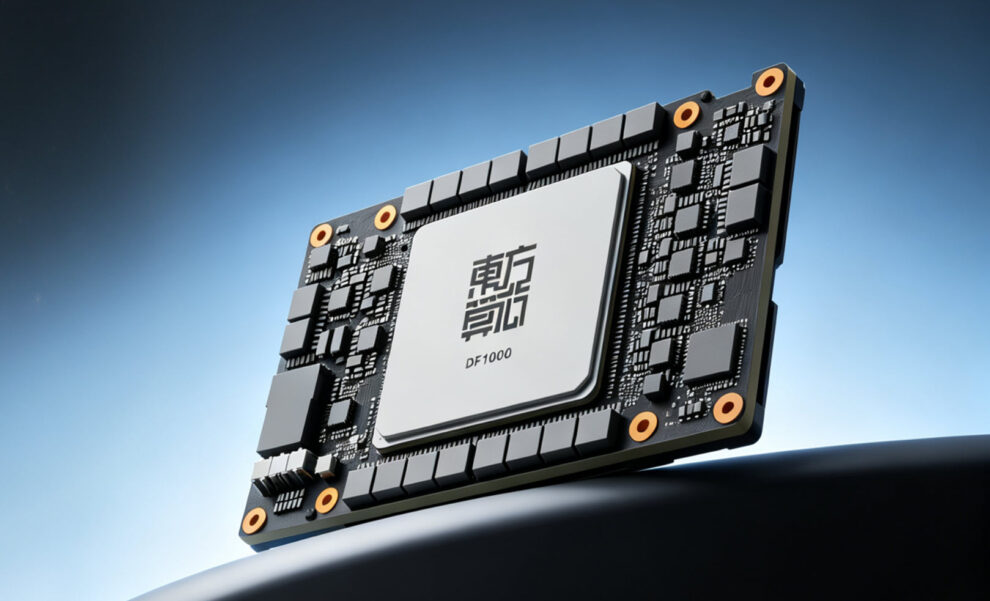
China DFSX has unveiled its TY64 SuperNode, a 14nm computing system that claims double the memory bandwidth of NVIDIA’s GB200 NVL72. Além disso, the announcement came through a technical disclosure that also detailed the system’s unconventional packaging. Ademais, the SuperNode skips traditional microbumps and instead uses vertical compute-memory towers, a design choice aimed at boosting performance. Consequentemente, this news places China DFSX among companies pushing the boundaries of high-bandwidth computing. No entanto, the source did not reveal commercial availability, pricing, or specific manufacturing partners. Ademais, the exact date of the announcement was not specified.
Key Specifications
- Memory bandwidth: 960 TB/s, doubling NVIDIA GB200 NVL72’s 576 TB/s
- Process node: 14nm
- Compute performance: 64 PFLOPS of BF16
- Packaging: Vertical compute-memory towers without microbumps
- Interconnect: 1.6T within the DF2000 chip
Memory Bandwidth: A Twofold Increase
According to the disclosed figures, the TY64 SuperNode achieves a memory bandwidth of 960TB/s. Ou seja, by comparison, NVIDIA’s GB200 NVL72 system offers 576TB/s, making the Chinese node exactly twice as fast in this metric.
Além disso, the fundamental unit is the DF2000 chip, each delivering 15TB/s of bandwidth. Portanto, the aggregated bandwidth result likely stems from a parallel arrangement of multiple such chips, though the exact configuration was not shared. No entanto, the total number of DF2000 chips in the node was not given. Ademais, the measurement conditions and sustained performance levels were not specified. Consequentemente, this bandwidth advantage is rooted in the SuperNode’s underlying chip architecture.
14nm DF2000 Chip Architecture
Each DF2000 chip is built using a 14nm fabrication process and incorporates multiple logic chiplets alongside stacked DRAM layers. Dessa forma, this heterogeneous integration allows dense packing of computing and memory resources. Ademais, the chip further boasts a 1.6T interconnect, enabling rapid data exchange.
Além disso, in terms of compute, the DF2000 is projected to hit 1000T of BF16 performance within this year. No entanto, no details were given about the chip’s die size, transistor count, or thermal envelope. Ademais, the specific foundry partner for the 14nm chips was not identified. Consequentemente, these chip-level features directly influence the system’s compute and memory performance.
Compute Performance: 64 PFLOPS of BF16
On a system level, the DF2000-based TY64 SuperNode delivers 64 PFLOPS of BF16 compute. Por outro lado, in stark contrast, the NVIDIA GB200 NVL72 reaches 360 PFLOPS BF16, more than five times the figure. Portanto, this discrepancy suggests a deliberate trade-off, favoring memory bandwidth over arithmetic throughput.
Além disso, the source indicated that the individual DF2000 can achieve 1000T BF16 this year, hinting at substantial compute headroom within each chip. No entanto, the precision of the BF16 compute (e.g., sparsity) was not detailed. Ademais, how this translates to the full SuperNode was not explained. Contudo, while compute power lags, the focus on memory bandwidth is intentional, as reflected in the packaging.
Vertical Towers Without Microbumps
One of the most notable aspects of the TY64 SuperNode is its packaging methodology. Ou seja, the system entirely eschews microbumps, a common element in advanced chip assemblies. Instead, it employs vertical towers that combine compute units and memory stacks. Consequentemente, this vertical orientation is intended to minimize physical distances and enhance signal integrity.
Além disso, the approach works in concert with the DF2000’s 1.6T interconnect to create a cohesive, high-bandwidth system. No entanto, the cooling solution for the vertical stacks was not described. Ademais, additional packaging details such as interposer materials or thermal management were omitted. Portanto, the innovative packaging is a key differentiator that may define the system’s real-world utility.
Future Implications and Roadmap
China DFSX has outlined a future where the DF2000 chip achieves 1000T BF16 compute, with the current SuperNode serving as a foundation. No entanto, the company has not announced any customer wins or production timelines for the TY64. Por outro lado, operating on a mature 14nm process could allow for quicker scaling if demand materializes.
Além disso, the target market segments, such as hyperscale data centers or edge, were not disclosed. Além disso, no benchmark comparisons beyond the stated numbers were provided. Além disso, the source provided no further roadmap beyond the chip-level compute target. Portanto, the SuperNode’s future will depend on execution and market acceptance.
Conclusion
Overall, the China DFSX TY64 SuperNode represents a distinctive entry in the high-performance computing landscape. Em resumo, its combination of 14nm technology, vertical packaging, and aggressive memory bandwidth targets sets it apart from conventional designs.
Frequently Asked Questions
What is the memory bandwidth difference between DFSX TY64 SuperNode and NVIDIA GB200 NVL72?
The DFSX TY64 SuperNode provides 960 TB/s memory bandwidth, ou seja, double the 576 TB/s offered by the NVIDIA GB200 NVL72 system.
How does the DFSX SuperNode achieve its high memory bandwidth?
Ou seja, it uses a 14nm design that skips microbumps, employing vertical compute-memory towers where each DF2000 chip delivers 15 TB/s bandwidth.
What are the BF16 compute capabilities of DFSX and NVIDIA systems?
Por outro lado, the DF2000-based TY64 SuperNode delivers 64 PFLOPS of BF16 compute, while the NVIDIA GB200 NVL72 achieves 360 PFLOPS.